01 / STUDY
Mechanism and experiments
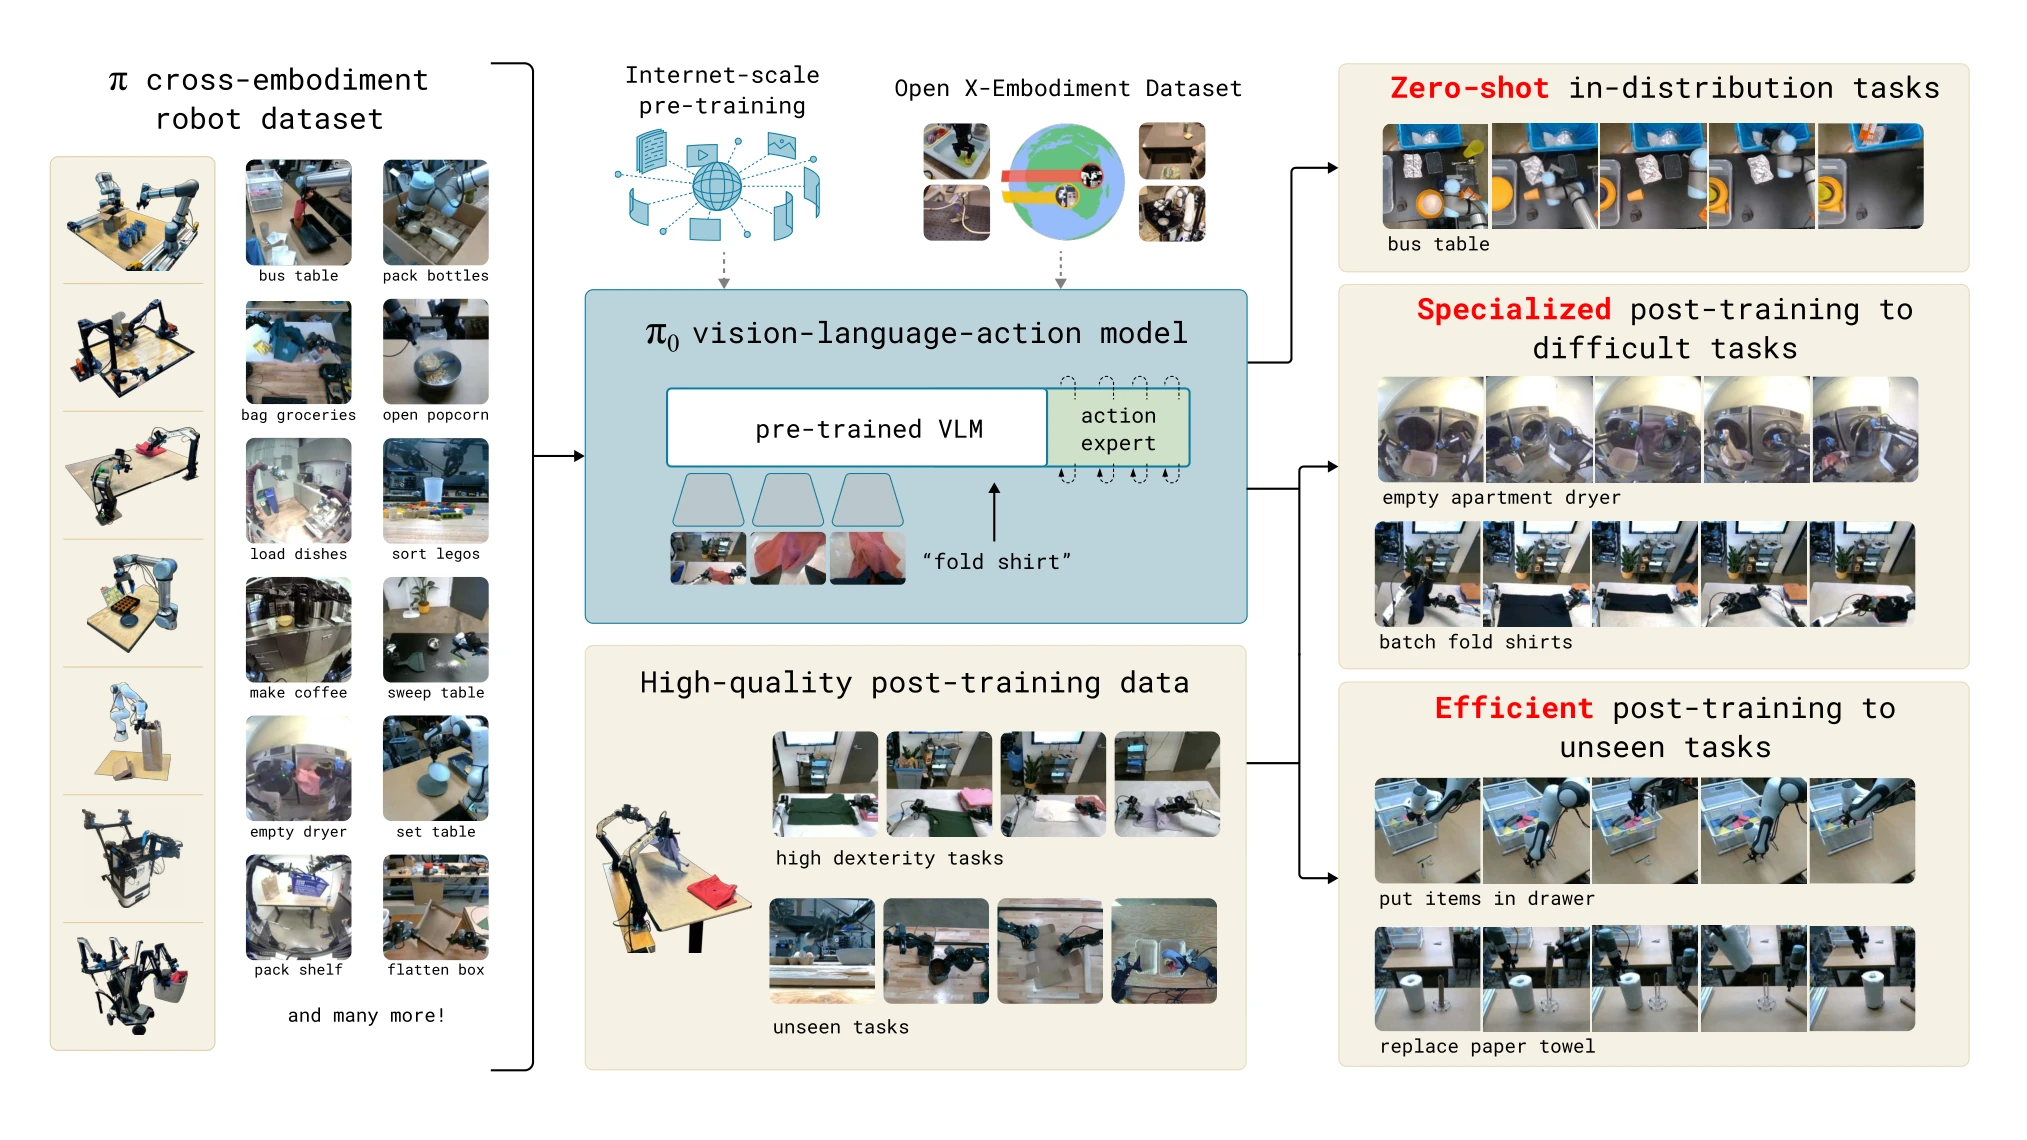
π₀ adds a flow-matching action component to a pretrained vision-language model and trains on data from several robots. The paper reports single-arm, bimanual and mobile-manipulation tasks. The openpi repository provides base models and selected task checkpoints, including an ALOHA towel-folding policy.
02 / CONTEXT
Test conditions and scope
Checkpoints target particular robots and tasks. Different cameras, grippers and control interfaces require adaptation and testing; the paper’s task coverage does not imply that all training data have been released.
03 / SOURCE